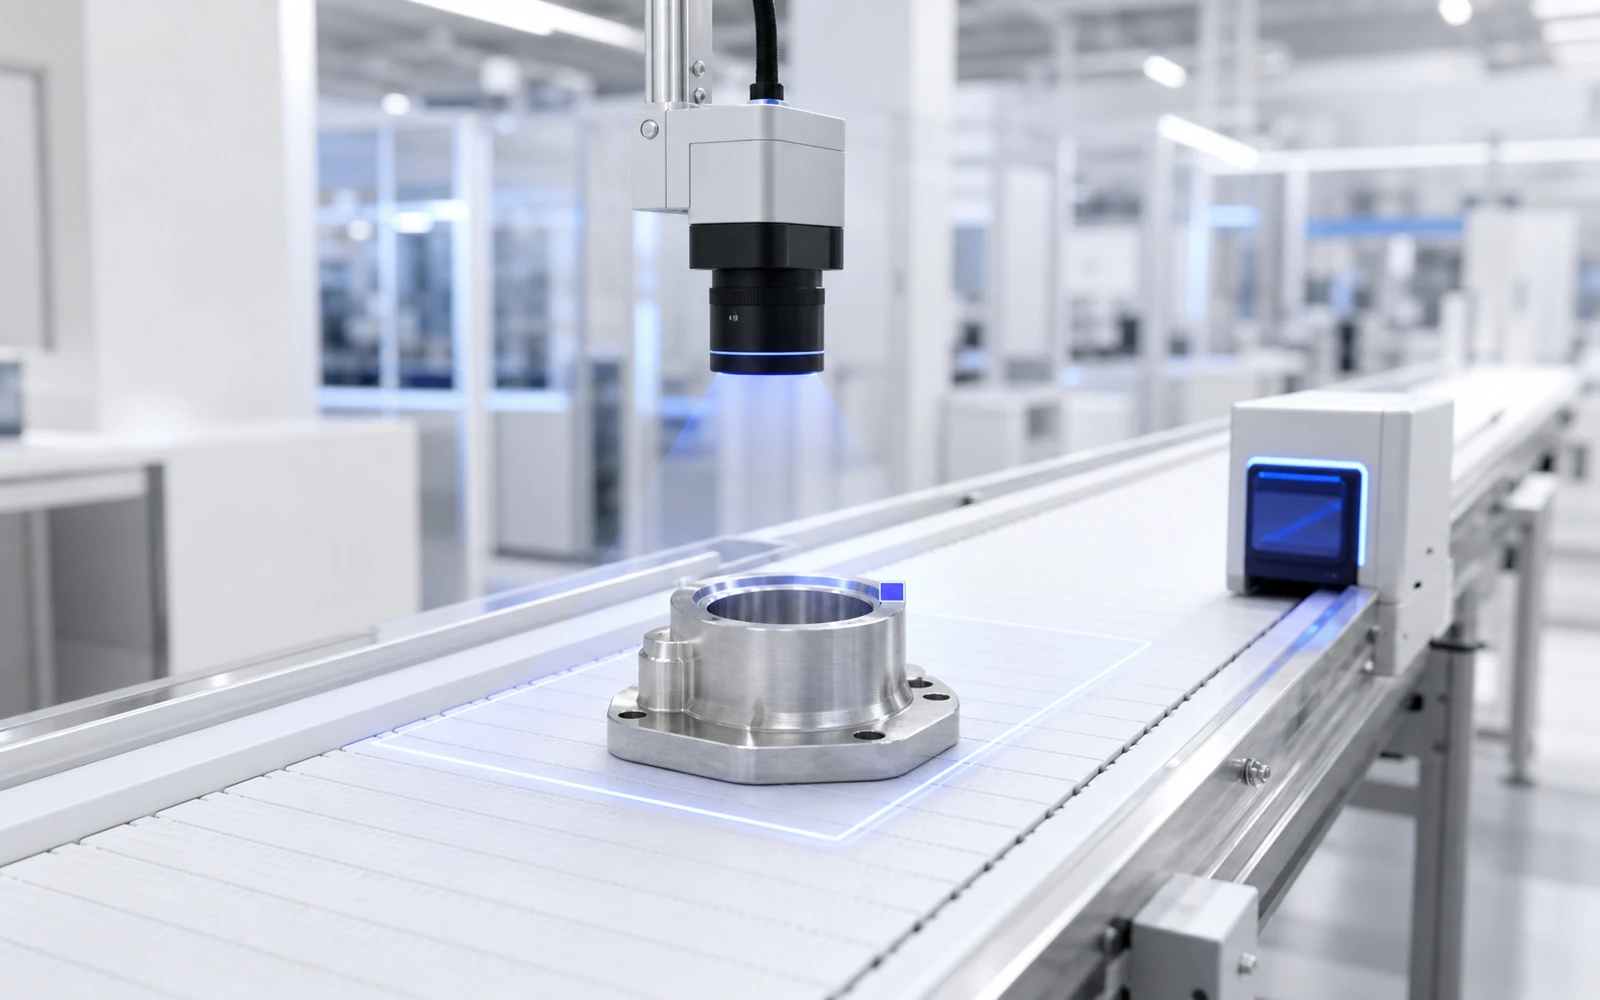
A visual inspection model that reaches 98% accuracy on a held-out test set can still be removed from a production line within a month. The model did not degrade. The line changed: a new supplier shipped parts with a slightly different surface finish, a lamp aged, the fixture that held the camera was bumped during maintenance, and a night shift began running the same product at a higher speed.
Quality inspection is not a classification problem with a camera attached. It is an operational system in which the model is one replaceable component. The parts that decide whether it survives - optics, lighting, defect definitions, threshold policy, update procedure, and the operator's ability to disagree with it - are mostly decided before anyone trains anything.
This article covers how to design that system: what to fix before collecting data, how to choose the vision task, where inference should run, how to set thresholds when a false accept and a false reject cost different amounts, and what a pilot has to prove before it earns a place on the line.
The Image Signal Comes Before the Model
Every downstream decision inherits the quality of the image. If the same part photographed twice produces two materially different images, no amount of model capacity will produce a stable decision.
Four variables dominate.
Lighting determines whether a defect is visible at all. A scratch on a brushed metal surface may be invisible under diffuse light and obvious under low-angle grazing light. Dark-field, bright-field, backlight, coaxial, and structured lighting each make a different defect class visible. Choosing the wrong geometry means the model is being asked to detect something that was never captured. This is not solvable in software.
Optics and working distance set the smallest defect you can resolve. If the acceptance criterion is a 0.2 mm chip and the pixel size at the object plane is 0.3 mm, the requirement cannot be met regardless of architecture. Compute the required resolution from the smallest defect and the field of view before selecting a camera, and keep several pixels across the smallest feature rather than exactly one.
Motion decides exposure. On a moving line, exposure time must be short enough that blur stays below the resolution requirement, which usually forces brighter illumination or a strobe synchronized to a trigger. A line that later runs 20% faster silently violates this budget.
Mechanical repeatability decides whether your training distribution still describes reality. Camera mounts drift. Fixtures are replaced. Vibration from a neighbouring machine changes with plant load.
The practical consequence is that image acquisition needs an acceptance specification, written before data collection, that states the required resolution at the object plane, the lighting geometry, the exposure and trigger scheme, and the mechanical tolerance for camera position. A calibration target imaged at the start of every shift, with automatic comparison against a reference, catches drift before it reaches the model.
Defect Definitions Are a Data Problem, Not a Labeling Task
Most inspection datasets are inconsistent, and the inconsistency usually comes from the plant rather than the labelers.
Ask three experienced inspectors to grade the same borderline part and you will often get three answers. That disagreement is real information about the acceptance criterion, not noise to be averaged away. If humans cannot agree, a model trained on their labels learns the average of an unresolved policy, and its decisions will look arbitrary to the very people expected to trust it.
Before labeling begins, the defect catalogue should be written with physical thresholds rather than adjectives - not "significant scratch" but "scratch longer than 2 mm or crossing the sealing surface." Each class needs boundary examples: the largest acceptable instance and the smallest rejectable one, photographed under the production lighting setup.
Measure agreement explicitly. Have two or three inspectors independently grade the same 200 parts and compute how often they match. Agreement below roughly 90% on a class means the class definition is the problem, and no model will exceed the ceiling that human inconsistency creates.
Ambiguous samples deserve their own path. Rather than forcing a binary label, route them to a second review and record the resolution. Over time these become the most valuable part of the dataset, because they define the boundary the model actually has to learn.
Choosing the Vision Task
Four formulations cover most inspection problems, and the choice changes both data cost and failure behaviour.
Classification assigns a label to the whole image - pass, fail, or a defect type. It needs the least annotation and works when a defect anywhere means rejection and the operator does not need to know where it is.
Object detection returns boxes around defects. It costs more to annotate but tells the operator where to look, which matters when the part will be reworked rather than scrapped, and lets you apply rules based on defect location.
Segmentation returns per-pixel masks and allows measurement - defect area, length, or proportion of a critical surface. Choose it when the acceptance criterion is dimensional, because that is the only formulation that lets a threshold be expressed in millimetres rather than in model confidence.
Anomaly detection trains mostly on good parts and flags deviation. It is the right starting point when defects are rare, diverse, or not fully known in advance - which is the normal condition for a new product line. The tradeoff is that it reports "unusual" rather than "defective," so it needs a human decision layer and produces more false alarms early on.
A common and defensible design combines them: anomaly detection as a wide net, followed by a classifier on flagged regions to separate real defect classes from benign variation.
Where Inference Runs
Placement is a latency and availability decision, not a preference.
Start from the cycle time. If a part passes the inspection station every 400 ms and the reject actuator needs its signal 150 ms before the part reaches it, the entire budget - trigger, capture, transfer, preprocess, inference, postprocess, decision - is 250 ms. Network round trips to a server, and especially to a cloud region, rarely fit.
Edge inference on an industrial PC or an embedded accelerator next to the line keeps latency bounded and keeps the line running when the network does not. It costs more per station, constrains model size, and makes updates a fleet-management problem.
Server inference on a plant-local machine centralizes GPUs across several stations and simplifies updates, but adds network dependency. It suits stations where the decision can be made a few seconds later - for example, marking a part in a database for downstream removal instead of triggering an immediate ejector.
Cloud inference is appropriate for offline analysis, retraining, and dashboards, and is almost never appropriate for the real-time decision itself.
Two rules survive most designs. The line must have a defined behaviour when inference is unavailable, and that behaviour must be chosen deliberately: pass everything and mark it for later review, reject everything, or stop. And whatever runs at the edge must report its model version with every decision, or you will be unable to explain a past result.
False Positives and False Negatives Are Not Symmetric
The two error types have different costs, and treating them as equivalent is the most common measurement mistake in inspection.
A false reject discards a good part. The cost is the part, the throughput, and - if it happens often - the operators' trust. Once a station is known for crying wolf, people begin overriding it by reflex, and the system stops functioning regardless of its metrics.
A false accept lets a defective part continue. Downstream the cost may be rework, a warranty claim, a recall, or a safety incident. In many plants a single escape costs more than a thousand unnecessary rejects.
That asymmetry should be expressed as an explicit cost ratio and used to set the decision threshold, rather than defaulting to a 0.5 cutoff or maximizing F1. If an escape costs 500 times a false reject, the operating point belongs far into high-recall territory, and the resulting false-reject rate is a deliberate purchase rather than a defect in the model.
Report the operating point, not just the curve. A precision-recall curve describes potential; the plant runs at one threshold, and that threshold, its cost assumptions, and the date it was last reviewed should be recorded next to the model version.
Confidence also needs calibration. A model that outputs 0.9 should be right about 90% of the time at that score, otherwise thresholds mean nothing across retrains. Check calibration whenever the model changes, and prefer to keep the threshold in the units the plant already uses - millimetres of defect, not arbitrary scores.
The Line Does Not Stop for a Model Update
A vision model in production is a versioned artifact with a rollback path, not a file someone replaces.
Every deployed decision should carry the model version, the preprocessing version, the threshold, and the calibration state at that moment. Without this, a quality investigation three months later cannot reconstruct why a specific part was passed.
New models should run in shadow mode before they decide anything: same images, predictions logged, no effect on the line. Comparing shadow predictions against the current model on live data reveals distribution problems that a static test set hides - particularly the case where overall accuracy improves while performance on one critical defect class drops.
Rollback must be one operation and it must be rehearsed. The realistic failure is not a dramatic crash; it is a new model that quietly raises the false-reject rate on the night shift, and the fix has to be available to whoever is on site at 03:00.
Retraining should be triggered by evidence rather than by a calendar. Useful triggers include a shift in the flagged-rate distribution, a rise in operator overrides, the introduction of a new part variant or supplier, and accumulation of enough newly reviewed ambiguous samples to change a class boundary.
Human Review Closes the Loop
Operator overrides are the highest-value data the system produces, and most installations throw them away.
When an operator disagrees with the station, capture the image, the model's output, the decision, the override, and - where possible - a short reason code. This produces a continuously refreshed set of exactly the cases the model finds hardest, labeled by the people whose judgement the system is meant to reproduce.
Watch the override rate as a first-class metric. A rising rate is an early warning that something upstream has changed, usually before the aggregate quality numbers move. A near-zero rate is also worth investigating; it often means operators have stopped looking rather than that the model became perfect.
The interface matters more than it appears. If recording a disagreement takes more than a couple of seconds, it will not happen during a busy shift, and the feedback channel silently closes.
Measure What the Plant Cares About
Model metrics belong in the engineering review. The operational review needs numbers the plant already manages.
The escape rate - defective parts that reached the next stage - is the metric that justifies the system, and it can only be measured against an independent check such as downstream audit sampling or customer returns. The false-reject rate translates directly into scrap and yield. Throughput impact answers whether inspection became the bottleneck. Station availability captures how often the line ran without a working inspection decision. Override rate tracks whether operators still trust the result.
Establish these numbers before deployment. A quality system with no pre-installation baseline cannot demonstrate improvement, only activity.
What a Pilot Has to Prove
A pilot that only shows a high test-set score has not reduced the risk that matters.
Scope it to one station, one product family, and one defect catalogue, and run it long enough to cross the sources of variation that actually exist - all shifts, multiple material lots, at least one maintenance event, and the seasonal or ambient lighting range if the station is exposed to it. A pilot that runs for three days on one lot under one lighting condition has tested almost nothing.
Define the exit criteria before starting, in operational terms: the escape rate on an audited sample, the acceptable false-reject rate at the chosen threshold, the decision latency at line speed, and the behaviour when inference is unavailable. Agree in advance what result would mean the project should not proceed. A pilot that cannot fail is a demonstration, not an evaluation.
Plan for the handover from the first day. Someone on site has to be able to recalibrate the station, read the logs, roll back a model, and explain a decision to a customer auditor. A system that only its builders can operate has not reached production, however well it scores.